Monday, February 10, 2014

Types of SQL Server Built-In Functions: Scalar, Grouped Aggregate, Window, Rowset

SQL Server offers many number of built-in functions for getting commonly required operations done, minimizing the time and resources need to implement them for handling business logics. These functions can be categorized with various classifications. One way of categorizing them is, understanding their scope of input and return type. Under this categorization, they can be organized into four groups: Scalar, Grouped Aggregate, Window, and Rowset. The organization of functions under this categorization makes some of functions member of more than one group.

Here is a small note on this categorization.

Scalar Functions
These functions accept zero or one or more than one value (or a row), process them as per its intended functionalities, and return a single value. These functions can be further categorized as string, conversion, mathematical, etc.. Some of these functions are deterministic  and some are nondeterministic. (Deterministic functions always return same result any time they are called with same input and same database state. Nondeterministic functions may return different result each time they are called with same input and same database state) Here are some examples for Scalar Functions;

  1. -- accepts no arguments
  2. SELECT GETDATE()
  3.  
  4. -- accepts one argument
  5. SELECT LEN('Hello World')
  6.  
  7. -- accepts multiple argument
  8. SELECT STUFF('accepts one argument', 9, 3, 'multiple')


Grouped Aggregate Functions

These functions perform their intended operations on a set of rows defined in a GROUP BY clause and return a single value. If GROUP BY is not provided, all rows are considered as one set and operation is performed on all rows. All aggregate functions are deterministic and ignore NULLs except the COUNT(*).

  1. -- Aggregate functions without GROUP BY
  2. SELECT COUNT(*), MIN(ListPrice), MAX(ListPrice)
  3. FROM Production.Product
  4.  
  5. -- Aggregate functions with GROUP BY
  6. SELECT YEAR(OrderDate) OrderYear, SUM(SubTotal) Total
  7. FROM Sales.SalesOrderHeader
  8. GROUP BY YEAR(OrderDate)


Window Functions

The operation of Window Functions are bit different from other functions. These functions produce a scalar value based on a calculation done on a subset of the main recordset. The subset used for producing the result is called as the Window. A different order can be defined for the window for performing the calculation without affecting the order of input rows or output rows. In addition to that, partitioning the window is also allowed.

Window is specified using OVER clause with its specification. SQL Server offers number of Window function for handling ranking, aggregation and offset comparisons between rows.

Here are few example on Window Functions;

  1. -- This uses SUM over Territory subsets (window)
  2. SELECT t.Territory, t.OrderYear, t.Total
  3.     , SUM(t.Total) OVER (PARTITION BY MONTH(t.Territory)) TotalByTerritory
  4. FROM (SELECT TerritoryId Territory, YEAR(OrderDate) OrderYear, SUM(SubTotal) Total
  5.     FROM Sales.SalesOrderHeader
  6.     GROUP BY TerritoryId, YEAR(OrderDate)) as t
  7. ORDER BY 1, 2
  8.  
  9. -- This uses ROW_NUMBER over all records
  10. SELECT SalesOrderID, SubTotal
  11.     , ROW_NUMBER() OVER (ORDER BY SubTotal) AS OrderValuePosition
  12. FROM Sales.SalesOrderHeader
  13. WHERE YEAR(OrderDate) = 2008
  14. ORDER BY SalesOrderID


Rowset Functions
Rowset functions accept input parameters and return objects that can be used as tables in TSQL statements. SQL Server offers four Rowset functions (OPENDATASOURCE, OPENQUERY, OPENROWSET, OPENXML) and they are nondeterministic functions.

Here is an example for it.

  1. -- Loading data from a text file
  2. -- as single BLOB
  3. SELECT * FROM
  4. OPENROWSET(BULK N'D:\TestData.txt', SINGLE_BLOB) AS Document

Saturday, February 8, 2014

Cumulative update package 8 for SQL Server 2012 Service Pack 1

Cumulative update #8 is available for SQL Server 2012 SP1. Refer the following link for downloading it and understanding the fixes done.

http://support.microsoft.com/kb/2917531

For more info on SQL Server versions and service packs, refer: http://dinesql.blogspot.com/2014/01/versions-and-service-packs-of-sql.html

TRY Counterparts for CAST, CONVERT and PARSE

For implementing explicit conversion from one type to another, we have been using either CAST or CONVERT functions given by Microsoft SQL Server. CAST is the standard ANSI way of converting and CONVERT is proprietary to Microsoft for converting. SQL Server 2012 introduces another function for converting string to date, time, and number, that accepts an additional argument for culture setting.

In addition to these three functions, CAST, CONVERT and PARSE have their counterparts called TRY_CAST, TRY_CONVERT, and TRY_PARSE. The different between them is, new functions return NULL for conversions with inconvertible input types instead of throwing errors.

Here is an example code;

  1. DECLARE @input varchar(10) = '1000'
  2.  
  3. -- these three SELECTs
  4. -- return values without
  5. -- any issue
  6. SELECT CAST(@input AS money)
  7. SELECT CONVERT(money, @input)
  8. SELECT PARSE(@input as money)
  9.  
  10. -- change the value
  11. SET @input = 'Thousand'
  12.  
  13. -- these three SELECTs
  14. -- throw errors
  15. SELECT CAST(@input AS money)
  16. SELECT CONVERT(money, @input)
  17. SELECT PARSE(@input as money)
  18.  
  19. -- these three SELECTs
  20. -- return NULLs
  21. SELECT TRY_CAST(@input AS money)
  22. SELECT TRY_CONVERT(money, @input)
  23. SELECT TRY_PARSE(@input as money)

What should we use? It depends on the way you need to handle it. If you need to continue the execution without any error, TRY_* is the best. However if the execution should be stopped with inconvertible data types, traditional conversion would be the best.

SQL Server DateTime data types, ranges, accuracy and default values

SQL Server offers different useful datetime data types for different purposes. Knowing all and their capabilities would definitely help you to decide the type to be used. Here are the most important properties of them. Click on the links for more information.

Data type Range from to Default value Accuracy
Date
(1-3 bytes )
0001-01-01 9999-12-31 1900-01-01 One day
Datetime
(8 bytes)
1753-01-01 9999-12-31 1900-01-01 00:00:00.000 Rounded to increments of .000, .003, or .007 seconds
Datetime2
(6-8 bytes)
0001-01-01 9999-12-31 1900-01-01 00:00:00.0000000 100 nanoseconds
datetimeoffset
(10 bytes)
0001-01-01 9999-12-31 1900-01-01 00:00:00.0000000 +00:00 100 nanoseconds
Smalldatetime
(4 bytes)
1900-01-01 2076-06-06 1900-01-01 00:00:00 One minute
Time
(5 bytes)
00:00:00.0000000 23:59:59.9999999 00:00:00.0000000 100 nanoseconds

Tuesday, February 4, 2014

SQL Server: Different ways of getting current date and time

What is the usual way of getting current date and time from SQL Server? Obviously, the answer is GETDATE function. Do you know that there are 7 different ways of getting the same with bit differences? Here are the ways and their differences;

Function Explanation
GETDATE() Returns datetime.
GETUTCDATE() Returns datetime in Universal Time Coordinated.
CURRENT_TIMESTAMP Returns datetime. This is ANSI Standard function
SYSDATETIME() Returns datetime2.
SYSUTCDATETIME() Returns datetime2 in Universal Time Coordinated.
SYSDATETIMEOFFSET() Returns datetimeoffset (time zone offset is included)
ODBC Canonical functions Not a standard way but they can be used too. There are many functions and NOW() is similar to GETDATE() which returns datetime. This has to be called as;
{fn NOW()}

  1. SELECT GETDATE() [GETDATE]
  2. SELECT GETUTCDATE() [GETUTCDATE]
  3. SELECT CURRENT_TIMESTAMP [CURRENT_TIMESTAMP]
  4. SELECT SYSDATETIME() [SYSDATETIME]
  5. SELECT SYSUTCDATETIME() [SYSUTCDATETIME]
  6. SELECT SYSDATETIMEOFFSET() [SYSDATETIMEOFFSET]
  7. SELECT {fn NOW()} [NOW]

image

Monday, February 3, 2014

New FORMAT function is slower than CONVERT function with dates?

SQL Server 2012 introduces many new string functions including CLR based functions. FORMAT is one of them which can be used for formatting dates, times and numeric. We have been using CONVERT function for formatting dates (refer this link for understanding different formatting: http://www.sqlusa.com/bestpractices/datetimeconversion/). However, with the introduction of new functions in SQL Server 2012, I see many recommendations on FORMAT function instead CONVERT. Question is, does it really help us on formatting?

FORMAT accepts date, time, and numeric values and returns a nvarchar value formatted based on format pattern specified with an optional cultural. In terms of usage, this is fairly easier than CONVERT, flexible, and many formatting options (See the syntax: http://technet.microsoft.com/en-us/library/hh213505.aspx). But what if it gives unexpected and poor performance?

Have a look on below code and the result. it is our traditional way for formatting the output. Note the time for completing the formatting on all records.

SELECT 
    SalesKey
    , CONVERT(varchar(20), DateKey, 104) AS Date
    , SalesQuantity
FROM dbo.FactSales

image

Here is the newest way.

SELECT 
    SalesKey
    , FORMAT(DateKey, 'd', 'de-de') AS Date
    , SalesQuantity
FROM dbo.FactSales

image

There is a clear indication that FORMAT does not give the same performance which CONVERT offers but the flexibility and additional options. Understanding the advantages and the fact that it relies on .NET framework CLR will definitely help you on writing efficient codes.

Sunday, February 2, 2014

What is “N” Prefix used with Unicode string?

If your database is multilingual, you are familiar with “N” prefix. Basically, we use “N” character as a prefix for string values when passing them to Unicode data type columns such as nchar and nvarchar. Question is, what is this “N” for?

UPDATE Production.Product
    SET Color = N'Black' -- nvarchar(15)
WHERE ProductID = 1

When this question is asked, most common answer is, “N” is for representing Nchar or Nvarchar. Unfortunately the most common answer is WRONG. “N” is not for Nchar or Nvarchar, it is for “National”.

Saturday, February 1, 2014

Instances that treat NULLs as equal values

NULLs in databases are considered as unknown values and can never be compared with another. This behavior (or the known fact) is common to Microsoft SQL Server too. That is the reason for failing queries written with an equality for NULLs;

USE AdventureWorks2012
GO
 
-- This returns no records
SELECT *
FROM Production.Product
WHERE Color = NULL

However, there are instances in SQL Server that treat NULLs as equal values. One instance is queries written with ORDER BY clause using nullable columns. ORDER BY treats NULLs as equal values and sorts them together. That is why we see NULLs at the top of the ordered results.

-- Products that have NULL for
-- Color will be appeared first
SELECT Name, Color
FROM Production.Product
ORDER BY Color

image

The other instance is, queries written with DISTINCT. DISTINCT treats NULLs as equal too. Because of that, you get only one record for NULLs if DISTINCT is based on a nullable column.

-- There will be one record
-- for all NULLs
SELECT DISTINCT Color
FROM Production.Product
ORDER BY Color

image

Monday, January 27, 2014

SQL String concatenation with CONCAT() function

We have been using plus sign (+) operator for concatenating string values for years with its limitations (or more precisely, its standard behaviors). The biggest disadvantage with this operator is, resulting NULL when concatenating with NULLs. This can be overcome by different techniques but it needs to be handled. Have a look on below code;

-- FullName will be NULL for
-- all records that have NULL
-- for MiddleName
SELECT 
    BusinessEntityID
    , FirstName + ' ' + MiddleName + ' ' + LastName AS FullName
FROM Person.Person
 
-- One way of handling it
SELECT 
    BusinessEntityID
    , FirstName + ' ' + ISNULL(MiddleName, '') + ' ' + LastName AS FullName
FROM Person.Person
 
-- Another way of handling it
SELECT 
    BusinessEntityID
    , FirstName + ' ' + COALESCE(MiddleName, '') + ' ' + LastName AS FullName
FROM Person.Person

SQL Server 2012 introduced a new function called CONCAT that accepts multiple string values including NULLs. The difference between CONCAT and (+) is, CONCAT substitutes NULLs with empty string, eliminating the need of additional task for handling NULLs. Here is the code.

SELECT 
    BusinessEntityID
    , CONCAT(FirstName, ' ', MiddleName, ' ', LastName) AS FullName
FROM Person.Person

If you were unaware, make sure you use CONCAT with next string concatenation for better result. However, remember that CONCAT substitutes NULLs with empty string which is varchar(1), not as varchar(0).

Friday, January 24, 2014

Business Intelligence: Dimensional Modeling - Do we need Operational Codes as Dimension Attributes?

Business User: I need the product code as product name, whenever I use product dimension, system should default to the code, not the name, we all are familiar with codes, not names.

Business Analyst: Will it be an issue for other users? Specifically the top management? I am sure that they do not want to see the revenue by code but revenue by product name.

Business User: I do not think that it is an issue, besides, we will be using the system not them, they will check main KPIs occasionally.

Business Analyst: BI solution is for all, not for one level, we will have the code for product dimension but let’s default to the name not the code, users who are familiar with codes can still go through codes, system facilitates …………

Business User: I think you don’t get what I say, isn't your duty managing users’ requirements……….

Okay, this could be a sort of conversation you will be having during the requirement gathering process or you might already have had something like this. How do you manage it? How did you manage it? What should be the best way of implementing this?

Dimension attributes are the keys of business intelligence solutions. The usability and understandability of attributes (same goes to dimensions too) measures the success of business intelligence solutions. If business users cannot understand or they cannot use the existing attributes for their analysis, the rejection rate goes up, making the solution less gravitative.

Here is an example: General Date dimension contains Year, Quarter, Month and Date. Some solution requires Week too. Once implemented, if bi-weekly analysis appears as another requirement, how it should be addressed? One solution is, have the week as the filter and filter out weeks for making its appearance as bi-weekly attribute. Though we provide a solution, business user sees it as technical solution, not as a business solution. The demand for bi-weekly attribute comes as no surprise. In the absence of business-user-aligned attributes, in the absence of business user’s most friendly attributes, solution becomes less useful.

Let’s go back to the conversation. Business Users insists the codes as the default attribute for product dimension. In most cases, the reason is, she/he comes from operational world. However, one user’s or one department’s requirement does not represent the entire organization’s requirement. Business Intelligence solution is not for a single person, not for one department. Arguing on this is not the way but explaining the advantages of usage of user-friendly textual, descriptive words for attributes will sort the matter. Explaining how these codes are inevitable for unnecessary inconsistencies will sort the matter. This does not mean that attributes such as product codes should completely ignored. This could be useful when preparing specific reports to operational business processes, this could be useful when communicating back to operational sources. Therefore make sure all attributes related to dimension are implemented and make most meaningful attribute as the default attribute. Not only that, make sure you spend more time on understanding attributes, naming them with accurate business terminology, and make them more robust.

Do not forget that neither measure or KPI can be analyzed without dimensions attributes. That is the starting point of all analysis, means that the success of a Business Intelligence solution is determined by dimensions’ attributes.

Monday, January 20, 2014

Can a query derive benefit from a multicolumn index for single-column filtering?

Assume that an index has been created using three columns. Will SQL Server use the index if the 2nd column is used for filtering?

I asked this question recently at a session, as expected, answer of majority was “No”. Many think that multicolumn index is not beneficial unless all columns are used for filtering or columns from left-to-right, in order, are used. Order is important but SQL Server do leverage the index even for 2nd and 3rd columns. If your answer for the question above is “No”, here is a simple example for understanding it.

USE AdventureWorksDW2012
GO
 
-- creating an index using 3 columns
CREATE INDEX IX_DimProduct_1 ON dbo.DimProduct
    (EnglishProductName, WeightUnitMeasureCode, SizeUnitMeasureCode)
 
-- filter using the first column
SELECT ProductKey, EnglishProductName
FROM dbo.DimProduct
WHERE EnglishProductName = 'Road-750 Black, 44'
 
-- filter using the second column
SELECT ProductKey, EnglishProductName
FROM dbo.DimProduct
WHERE WeightUnitMeasureCode = 'G'
 
-- filter using the third
SELECT ProductKey, EnglishProductName
FROM dbo.DimProduct
WHERE SizeUnitMeasureCode = 'CM'
 
-- cleaning the code
DROP INDEX IX_DimProduct_1 ON dbo.DimProduct

This code creates an index using three columns. As you see, the SELECT statements use the columns used for the index; first SELECT uses EnglishProductName, second uses WeightUnitMeasureCode, and third uses SizeUnitMeasureCode. Have a look on query plans;

image

Plans clearly show that SQL Server leverages the index for all three SELECT statements. However, note the way it has been used. For the first SELECT, Index Seek has been used but Index Scan for the second and third. This means, filtering with left-most columns gets more benefits but filtering with right-most columns do not get it optimally.

See below query, filtering starts on the left-most column and two columns are used. As you see, it is “Index Seek”; Index is used optimally.

-- filter using the first and second columns
SELECT ProductKey, EnglishProductName
FROM dbo.DimProduct
WHERE EnglishProductName = 'Road-750 Black, 44' 
    AND WeightUnitMeasureCode = 'G'

image

Tuesday, January 14, 2014

Why column aliases are not recognized by all clauses?

Column aliases are commonly used for relabeling columns for increasing the readability of SQL statements. However aliases cannot be referred with all clauses used in SQL statements. Have a look on below code and its output.

1 SELECT 2 GroupName AS DepartmentGroup 3 , COUNT(Name) AS NumberOfDepartment 4 FROM HumanResources.Department 5 GROUP BY DepartmentGroup

Output:
Msg 207, Level 16, State 1, Line 5
Invalid column name 'DepartmentGroup'.

As you see, GROUP BY clause does not recognize the alias “DepartmentGroup” used for GroupName column. Not only GROUP BY, WHERE and HAVING clauses do not recognize aliases too. You can simply refer the same column name with these clauses without thinking much, however knowing the reason for this will definitely add something to your knowledgebase. Not only that, it will help you to properly construct your SQL statements too.

Possible ways of aliasing columns
There are three ways of aliasing columns with identical output results. One method is to use AS keyword, next is to use equal sign (=), and the other way is positioning the alias immediately following the column name.

1 SELECT 2 GroupName AS DepartmentGroup 3 , COUNT(Name) AS NumberOfDepartment 4 FROM HumanResources.Department 5 GROUP BY GroupName 6 7 SELECT 8 DepartmentGroup = GroupName 9 , COUNT(Name) AS NumberOfDepartment 10 FROM HumanResources.Department 11 GROUP BY GroupName 12 13 SELECT 14 GroupName DepartmentGroup 15 , COUNT(Name) AS NumberOfDepartment 16 FROM HumanResources.Department 17 GROUP BY GroupName

In terms of performance, there is no difference between these three methods but readability. Most prefer AS keyword and it is the recommended way by industrial experts.

Why all clauses cannot refer aliases added?
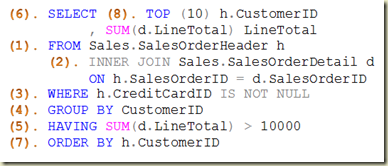
This is because of the logical order query processing. Clauses like GROUP BY, WHERE, and HAVING are processed prior to SELECT. Therefore the aliases used are unknown to them. Below image shows a SELECT statement. Elements in it are numbered based on the processing order.

Order

Note that you can refer aliases with ORDER BY. The reason for it is, ORDER BY (7) is processed after the SELECT (6). Read more on this at: http://dinesql.blogspot.com/2011/04/logical-query-processing-phases-in.html.

Aliases for expressions: Should I write it again with GROUP BY?
We assign aliases for expressions used in SELECT. However, as the alias cannot be referred with a clause like GROUP BY, same expression has to be duplicated which increases the cost of maintainability. It can be overcome by implementing a table expression without hindering the performance.

1 -- expression is set with 2 -- both column and group by 3 SELECT 4 YEAR(OrderDate) OrderYear 5 , SUM(SubTotal) TotalAmount 6 FROM Sales.SalesOrderHeader 7 GROUP BY YEAR(OrderDate) 8 9 -- expression is set only with 10 -- the column 11 SELECT 12 OrderYear 13 , SUM(SubTotal) TotalAmount 14 FROM (SELECT 15 YEAR(OrderDate) OrderYear 16 , SubTotal 17 FROM Sales.SalesOrderHeader) Sales 18 GROUP BY OrderYear
Aliases for tables
It is possible to have aliases for tables too. It does not support all three ways but AS keyword and adding right after the table name. Here is an example;

1 SELECT Orders.OrderDate 2 , Orders.SubTotal 3 FROM Sales.SalesOrderHeader AS Orders 4 5 SELECT h.PurchaseOrderNumber OrderNumber 6 , p.Name Product 7 , d.LineTotal 8 FROM Sales.SalesOrderHeader h 9 INNER JOIN Sales.SalesOrderDetail d 10 ON h.SalesOrderID = d.SalesOrderID 11 INNER JOIN Production.Product p 12 ON d.ProductID = p.ProductID

Sunday, January 12, 2014

SQL Server Management Studio – Five ways of executing a code

How many ways you have used for executing a T-SQL code in Management Studio? I am sure you have used two well-known options but other three options are unknown to many. Here are all five ways;

  1. Clicking Execute button in SQL Editor toolbar.
  2. Pressing F5 key in keuboard.
  3. Pressing CTRL+E shortcut key.
  4. Pressing CTRL+SHIFT+E shortcut key.
  5. Pressing ALT+X shortcut key.

Analysis Services: Exception of type 'System.OutOfMemoryException' was thrown.

There could be many reasons for this but in most cases, this misleads us, specifically if the MDX is running with Management Studio. You see that there is enough memory, and you are confident of the MDX, but why the Management Studio throws this?

Reason is simple. This Knowledge base article explains it;

“SSMS is a 32-bit process. Therefore, it is limited to 2 GB of memory. SSMS imposes an artificial limit on how much text that can be displayed per database field in the results window. This limit is 64 KB in "Grid" mode and 8 KB in "Text" mode. If the result set is too large, the memory that is required to display the query results may surpass the 2 GB limit of the SSMS process. Therefore, a large result set can cause the error that is mentioned in the "Symptoms" section.”

How do we make sure that MS throws the exception because of its limitations, not because of anything else. Simplest way is, get the code executed using another technique. It can be a .NET code using a provider that supports executing MDX against SSAS or could be a SSIS package. I used a simple SSIS package that has a connection to source and data reader destination. Here is the way;

  1. Create a new SSIS project and add an OLE DB Connection to SSAS.
    image
  2. Make sure you add “Format=Tabular” for Extended Properties in Connection Manager.
    image
  3. Add a data flow task and configure an OLE DB Source.
  4. Set the SSAS connection made to OLDE DB Source and add the MDX statement as SQL Command.
  5. Add a Data Reader destination and connect with the source.
  6. Execute and see.
    image

If the code gets executed without any issue, it means you are hit by SSMS limitation not because of anything else.

Versions and Service Packs of SQL Server (2012, 2008 R2, 2008, 2005)

Have you installed all service packs and necessary patches for all your SQL Server instances? Check the version with this table, if not, get them downloaded and installed.

SQL Server Code Name Initial Version Service Packs
2014

Hekaton

12.00.2000.8

CU1: 12.0.2342.0
CU3: 12.0.2402
2012

Denali

11.00.2100

SP1: 11.00.3000
SP1: CU#7: 11.0.3393
SP1: CU#8: 11.0.3401
SP1: CU#9: 11.0.3412
SP2: 11.0.5058
SP2: HotFix – 11.0.5522
SP2: CU#1: 11.0.5532

2008 R2

Kilimanjaro

10.50.1600.1

SP1: 10.50.2500
SP2: 10.50.4000
SP2: CU#11: 10.50.4302
SP2: CU#12: 10.50.4305
2008

Katmai

10.00.1600.22

SP1: 10.00.2531
SP2: 10.00.4000
SP3: 10.00.5500
SP3: CU#14: 10.00.5848
2005

Yukon

9.00.1399.06

SP1: 9.00.2047
SP2: 9.00.3042
SP3: 9.00.4035
SP4: 9.00.5000
SP4: CU#3: 9.00.5266

Here are couple of ways of determining the version of your SQL Server instance;

1. SQL Server Management Studio: Object Explorer

image

2. @@VERSION global variable

image

3. SERVERPROPERTY function

image

Friday, January 3, 2014

Demo links for SS SLUG Dec 2013 - Brain Bashers

Demo 1: Filtering DateTime values – SS SLUG Dec 2013 – SQL Brain Bashers - Demo I

Demo 2: How SQL Server interprets two-digit years as four-digit years – SS SLUG Dec 2013 – Brain Bashers - Demo II

Demo 3: Best way to pass datetime values to SQL Server – SS SLUG Dec 2013 – Brain Bashers - Demo III

Demo 4: Can we commit inner (or nested) transactions?– SS SLUG Dec 2013 – Brain Bashers - Demo IV

Demo 5: http://dinesql.blogspot.com/2010/02/understanding-grouping-sets.html

Demo 6: Are you calculating Average correctly?

Demo 7: DBCC CHECKIDENT does not reset identity value as you need?

Demo 8: Ordering the result of Views – SS SLUG Dec 2013 – Brain Bashers - Demo VIII

Link for the presentation: {Pending}

Why SQL Server splits the page? I am changing an integer value.

If someone asks “Why SQL Server splits pages”, I know that all of you say “If an insert or update requires more space, SQL Server splits the page and moves half of the records to the new page”. It is true. This makes the table externally fragmented too. However, can there be a scenario which an change of integer value splits the page? There can be, and here it is.

Before that, if you need to understand page-split and fragmentation, read this: http://dinesql.blogspot.com/2013/08/understanding-index-fragmentation-ss.html.

We will start with a simple code. Have a look on below code;

USE tempdb
GO
 
-- creating test table
CREATE TABLE dbo.TestTable
(
    Id int PRIMARY KEY
    , Value char(4000) NOT NULL
)
GO
 
-- inserting 2 records
INSERT INTO dbo.TestTable
    VALUES 
    (2, replicate('a', 4000)), (5, replicate('b', 4000))
 
-- check records with page numbers
SELECT Id, Value, ph.*
FROM dbo.TestTable
CROSS APPLY fn_PhysLocCracker(%%PHYSLOC%%) ph

I have used two functions for getting page numbers related to inserted records. For more info on these two functions, read this: http://dinesql.blogspot.com/2013/12/finding-pages-or-physical-location-of.html

Here is the result of the SELECT;

image

As you with the result, both records are in same page, and becuase of the size of records, page is almost full. Let’s do a modification to Value column first and see whether it causes a page split.

UPDATE dbo.TestTable
    SET Value = replicate('e', 4000)
WHERE id = 2
 
SELECT Id, Value, ph.*
FROM dbo.TestTable
CROSS APPLY fn_PhysLocCracker(%%PHYSLOC%%) ph

image

Result is same. Getting 4000 bytes as a changed value has not required additional space and page split has not occurred. Now let’s make a change on Id column.

UPDATE dbo.TestTable
    SET Id = 3
WHERE id = 2
 
SELECT Id, Value, ph.*
FROM dbo.TestTable
CROSS APPLY fn_PhysLocCracker(%%PHYSLOC%%) ph

image

Page split has occurred. Why SQL Server needs space and splits the page ONLY IF IT IS AN INTEGER COLUMN? This is what you have understand. Note that this is not just an integer column. It is the PRIMARY KEY; The clustered key. What happened was, SQL Server updated the Value column as an in-place update. It does not require additional space. However SQL Server does not perform in-place update for key columns. It performs delete-plus-insert operation for key column updates. It requires space for the INSERT. That is the reason for the page split. Understand that this behavior is not only for integer, it is for all key columns.

I will make another post on in-place update and delete-plus-insert operation.

Wednesday, January 1, 2014

Ordering the result of Views – SS SLUG Dec 2013 – Brain Bashers - Demo VIII

First of all, Happy New Year 2014! May your all dreams come true in 2014!

This post is related to the presentation “SQL Brain Bashers” I did at SQL Sever Sri Lanka User Group Meeting. This topic is very old but still it needs to be discussed for beginners; it is all about having ORDER BY with VIEWs.

Here is the question related to this demo;

Does SQL Server sort the resultset returning from a view based on ORDER BY clause added?

Answer is “NO”. Have a look on below code and then see the explanation.

USE AdventureWorks2012
GO
 
-- this throws an error
-- read the error properly
CREATE VIEW v_SalesOrdersDetails
AS
SELECT SalesOrderID, SalesOrderDetailID
    , CarrierTrackingNumber, OrderQty
    , ProductID, LineTotal
FROM Sales.SalesOrderDetail
ORDER BY ProductID DESC
GO
 
-- this creates the view
CREATE VIEW v_SalesOrdersDetails
AS
SELECT TOP 100 PERCENT 
    SalesOrderID, SalesOrderDetailID
    , CarrierTrackingNumber, OrderQty
    , ProductID, LineTotal
FROM Sales.SalesOrderDetail
ORDER BY ProductID DESC
GO
 
-- this query does not sort the
-- result by product id
SELECT * FROM v_SalesOrdersDetails 
 
-- this sorts as we have added
-- to the query
SELECT * FROM v_SalesOrdersDetails 
ORDER BY ProductID DESC 

Here is the result;

View

As you see, the ORDER BY clause we have added to the view has no effects.

Let’s try to understand this behavior. Remember the error thrown from first try. It clearly says that ORDER BY cannot be used with VIEWs. Looks weird :)? There is nothing wrong with it. View is supposed to represent a table. A table is a logical entity that does not hold ordered rows, hence view cannot hold ordered rows too. However SQL Server allows to use ORDER BY clause with views when TOP or FOR XML is used. Again, remember, though you have used ORDER BY with TOP, it does not sort the result, it uses ORDER BY for completing TOP operation only (Note: Generally it uses ORDER BY for two purposes; Which rows to be picked for the TOP, and order the result).

There is a misconception that adding TOP 99.99 PERCENT sorts the result set based on ORDER BY added. The fact is, it is wrong too, SQL Server does not guarantee a sorted resultset. Not only that, the result set might not contain all records returned.